


It is pretty rare for me to spend three days at a conference. But having finished up a contract consulting role and after a week’s holiday in Greece, I was ready. AI Engineer Europe, the first major European AI engineering conference in years, ran April 8-10 in London. There were a few teething issues at the start, which meant I missed half the first day’s morning, but I managed to get roughly 20 sessions in across keynotes, technical deep-dives, and practitioner case studies.
This was a conference aimed at engineers and more technical than my usual events. I didn’t feel out of place though, perhaps a sign that AI has bridged the gap for me. Developers are leading the charge on AI, so it felt important to get deep amongst this crowd to understand how it all translates to knowledge work, and specifically investment workflows.
The Headline: Models Are Good Enough. You Are Not Ready.
The recurring signal across every session was striking in its consistency. The gap between AI demos and production-ready systems is not a model capability problem. It is a human and systems problem.
Models are good enough. What is lagging is everything around them: evaluation frameworks, context engineering, governance, domain expertise, and organisational design. The teams who build that infrastructure now will compound the advantage over the next two to three years. This is a new way of working: leveraging technology, not just adding headcount.
As models commoditise, value shifts upward into the application layer: workflow design, domain integration, interfaces, memory, evals, orchestration. The implication is that the edge will not come from having access to the best model. It will come from the application layer built around it.
For investment professionals experimenting with AI workflows, this reframe matters.
Here are the four themes that showed up repeatedly, and why each one maps directly to what we do.
Evals Are the Missing Discipline
There was a lot of focus on evaluations, or evals. For those who don’t know the term: it’s short for evaluation. Basically a framework for testing whether AI agents are acting as expected and producing correct output. In broad terms it’s simple: is the agent doing what you need it to do?
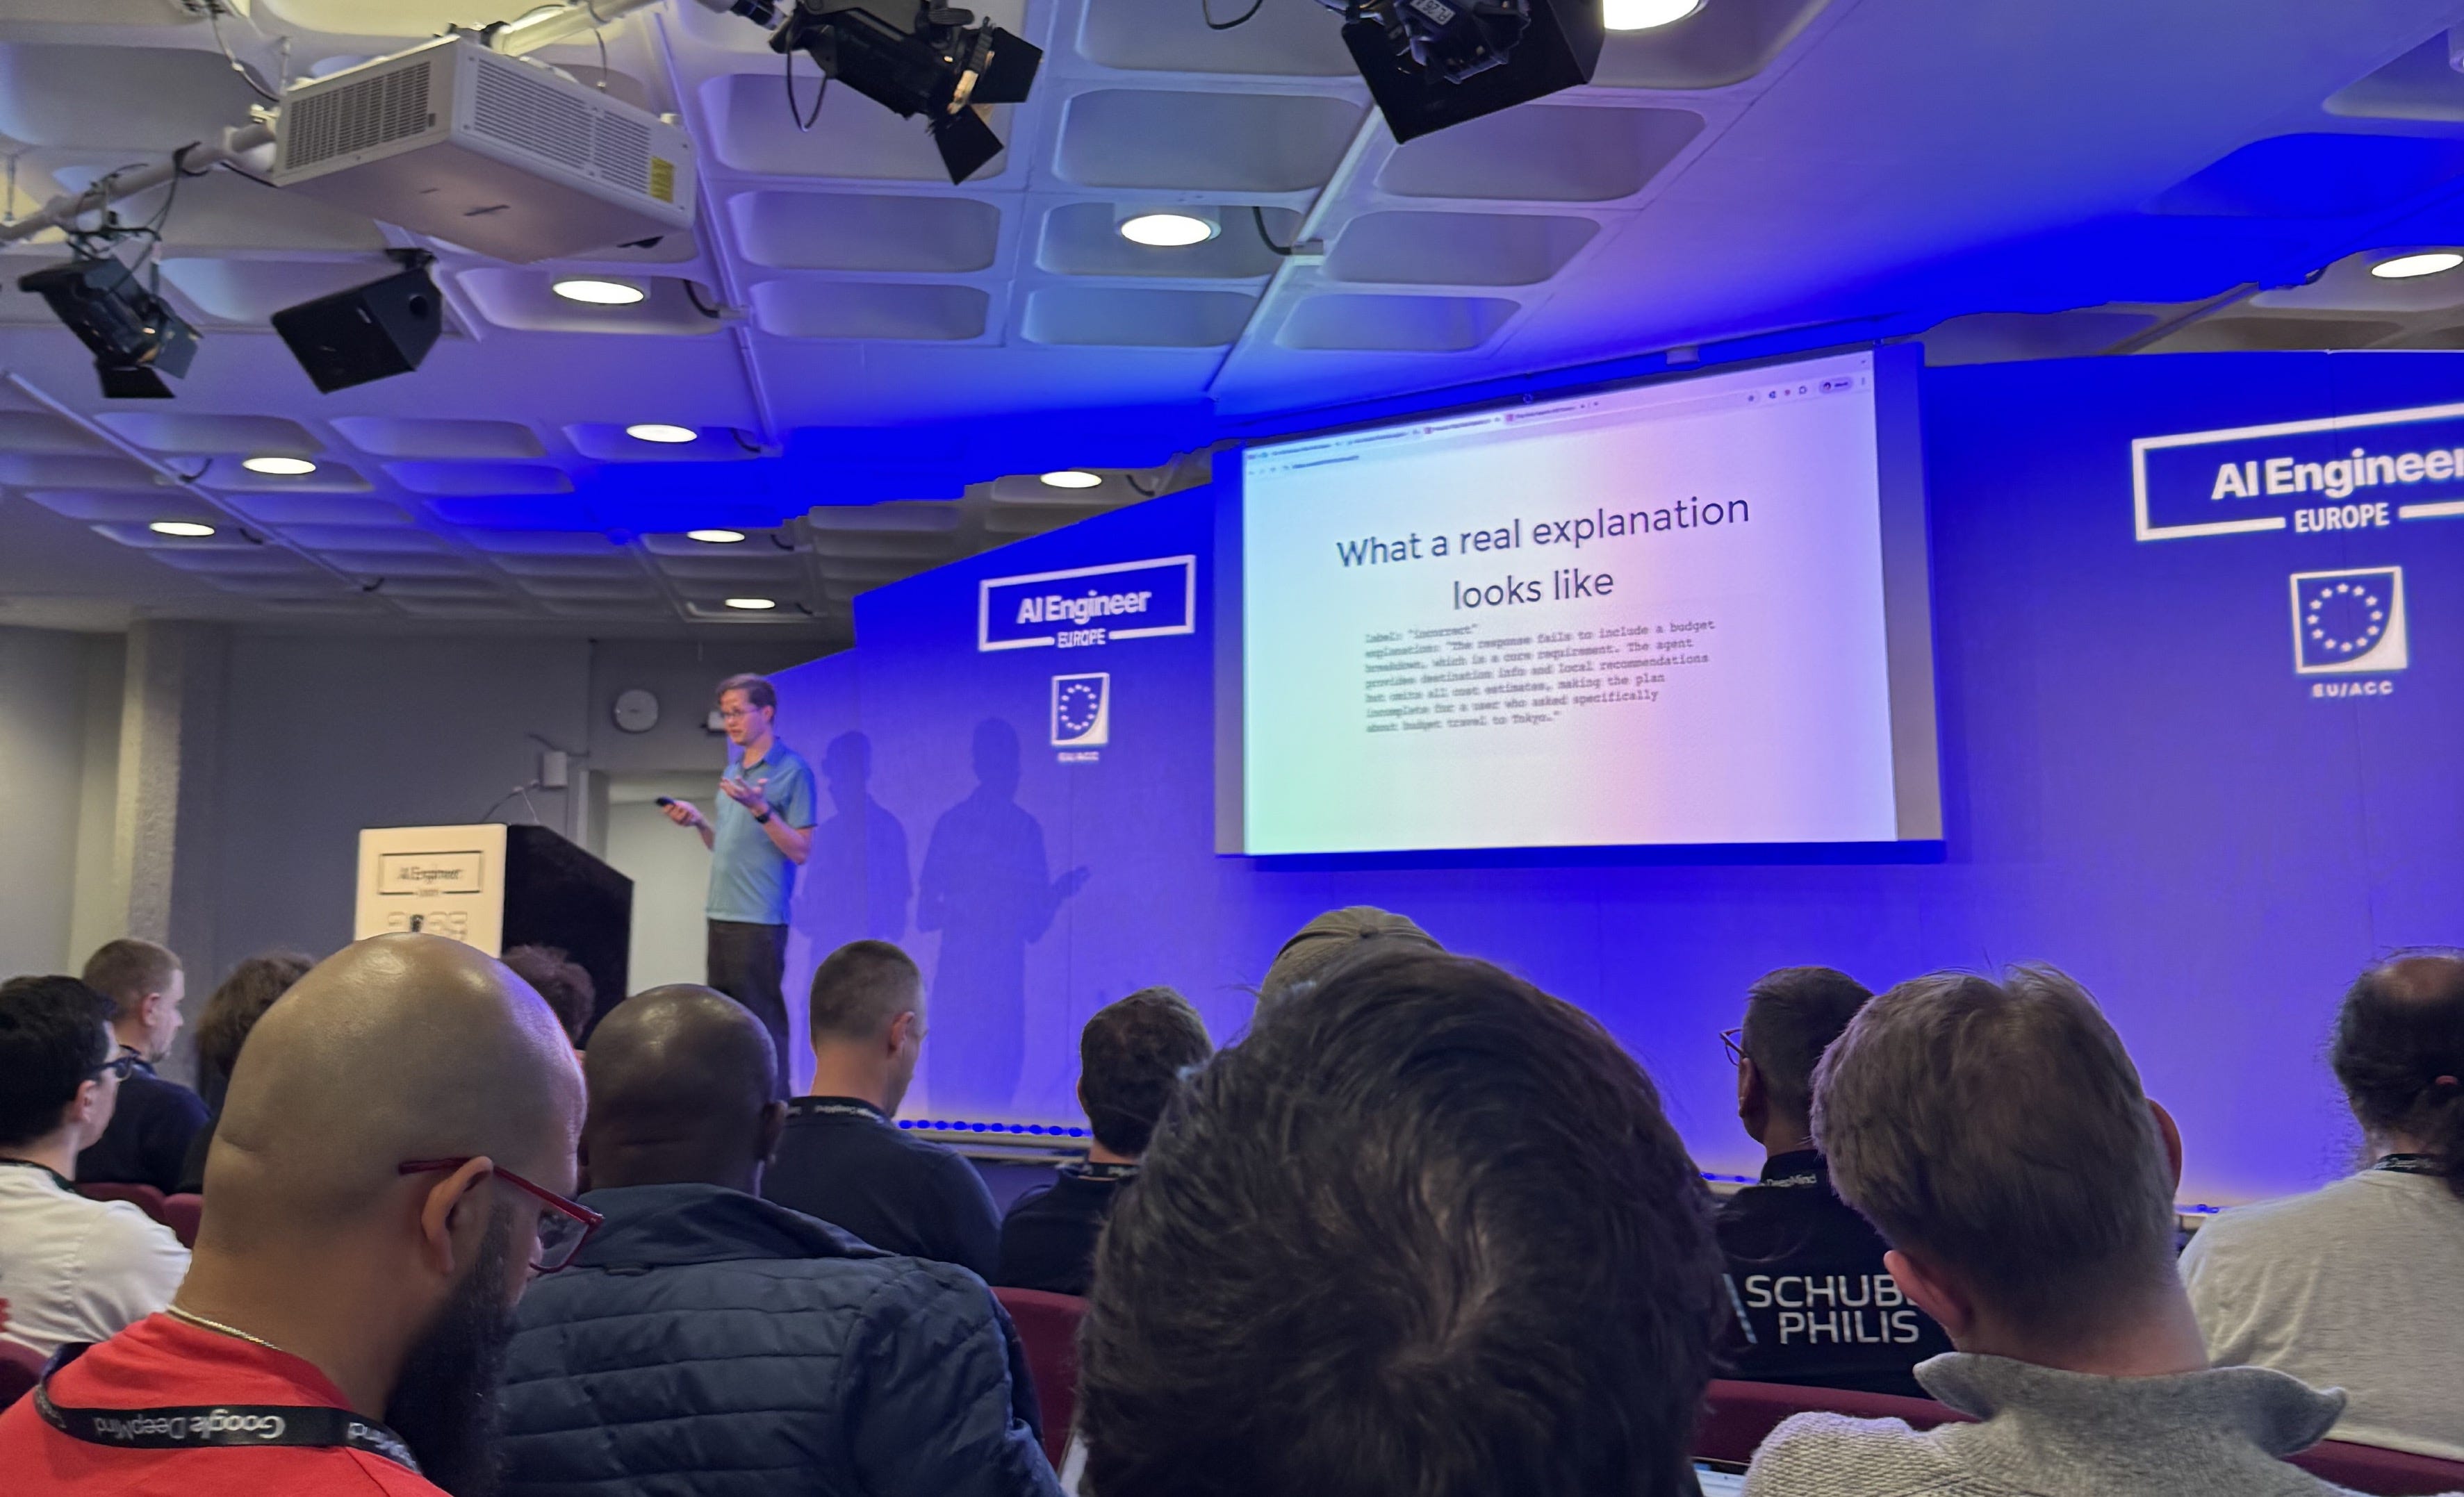
I attended a workshop on the first day where the Arize AI team walked through evaluation frameworks for agentic applications, and the takeaway was blunt: without systematic evaluation, you are flying on vibes. That’s where most investment teams are now. None are running evals on their prompts.
They laid out a layered approach. Code evals first: deterministic, free, fast. Then LLM-as-judge for semantic assessment. Then human review as the gold standard. No single layer catches everything. They called it the Swiss Cheese Model: stack the layers, and each one catches what the others miss.
They demonstrated a basic eval to test whether a research report contained a recommendation. That’s a good starting point, but evaluating AI agents in investment workflows will require more work. You need domain expertise, a subject matter expert who can determine what makes a good report. Something I plan to experiment with.
Here is what most teams get wrong. They blame the model when the output is poor. But the session made a point I have seen in my own builds: infrastructure bugs look like reasoning failures. Check the plumbing before you blame the model. A broken data feed or malformed context will produce garbage that looks like the AI is hallucinating, when really it never had the right inputs.
The practical implication: building a golden dataset from a starting set of 20 real research outputs, labelling them pass or fail with critique, is a weekend project. Not a multi-month programme. If you are running any AI-assisted research workflow and you do not have evals, start there. [Phoenix](https://phoenix.arize.com/), Arize’s open-source observability tool, is a good place to begin.
Context Engineering, Not Prompt Dumping
There was a whole track at the conference dedicated to context engineering. Patrick Debois, the creator of DevOps, gave what I think was the most conceptually important talk. His argument: context is the primary lever determining what agents produce, and it deserves the same engineering rigour as code.
He laid out a Context Development Lifecycle: Generate, Evaluate, Distribute, Observe, and loop. Humans as context engines. Reusable prompts. Rules files. Context drawn from the codebase, documentation, and institutional knowledge. Then you evaluate that context (syntax checking, validation, even CI/CD pipelines for context changes), distribute it through shared repos and registries, and observe how agents use it.
This is similar to how I’ve been thinking about context, which I discussed in a previous issue on building a second brain and updating it as you continue to work with AI. This context compounds, and becomes even more important when distributed within a team implementing AI in investment workflows.
The phrase that stuck: throwing a long system prompt at an agent is not context engineering. It is prompt dumping.
For investment teams, this reframes the entire AI adoption conversation. Most teams I speak to are still at the “paste the company filing into ChatGPT” stage. That is prompt dumping. Context engineering means versioning your research templates, thesis frameworks, and sector knowledge as carefully as you version your models. It means building a context flywheel: from individual use, to team shared understanding, to multi-team, to organisation-wide.
The teams that build this discipline will produce consistently better AI-assisted research. The ones that do not will keep getting inconsistent results and blaming the model.
Domain Expertise Is Non-Negotiable
Chris Lovejoy, a medical doctor turned AI engineer, presented the clearest framework I have seen for where human judgment sits in an AI workflow. He described three roles: the Oracle (directly assesses and improves outputs), the Evaluator (defines and measures quality), and the Architect (builds self-improving systems).
In investment research, the domain expert is the PM or analyst. The Oracle role is obvious: you need someone who can look at AI-generated research and say “this is wrong because the margin assumption ignores the regulatory change announced last quarter.” No model can do that reliably. The failure mode I see constantly: teams build AI prototypes without anyone in the room who can actually assess output quality. They end up with impressive demos that produce unreliable work.
This was reinforced by the Spreadsheets for Agents session, which traced a journey from 50% to 92% accuracy over four months and multiple architecture changes. The key finding: financial domain knowledge improved results on every single task and outlived every tool change. They tried SQL views, XML, custom tool sets. All dead ends. What persisted was the domain knowledge layer.
The lesson is clear. If you are building AI into an investment workflow, the domain expert is not optional. They are the foundation. Hire for it, embed it, and make it a first-class role in the team.
Progressive Autonomy: Shadow Mode First, Always
I wasn’t expecting much from the Accenture team, who seemed a bit out of place at an engineering conference. But they presented a framework that made a lot of sense for any enterprise deploying AI: Shadow Mode to Advisory to Controlled Autonomy to Expanded Autonomy. Never deploy agents at full autonomy from day one. The reason is straightforward: agent reliability is genuinely hard. Too many moving parts, bad tooling that looks like reasoning failure, errors that cascade across multi-step workflows, and trust that depends entirely on reversibility and visibility.
This maps directly to the self-driving car analogy I have used in earlier issues. Shadow Mode is cruise control: the AI runs alongside humans, and you compare outputs. Advisory is assisted driving: the AI makes recommendations, a human approves. Controlled Autonomy is narrow, low-risk tasks delegated to the agent. Expanded Autonomy is the end state, gated by evidence and outcomes.
What the Accenture team added to this was the organisational layer. The reason most enterprise AI projects fail is not that the AI failed. It is that the project could not justify certainty upfront. Large enterprises have been set up to be run by humans, not by AI agents. Experimentation needs to be encouraged and fostered. Without it, traditional finance and governance frameworks kill emergent projects. Their proposal: the CEO should think like a VC partner. A portfolio of bets, not monolithic projects.
Governance speed, they argued, must become an engineering problem, not a process problem. For investment teams operating under compliance constraints, this framing is essential. You cannot deploy AI in a big-bang launch. But you can run a shadow mode pilot that builds the evidence base for expanding autonomy over time.
What Else Stood Out
These are not the main takeaways for most readers, but worth flagging for anyone tracking the infrastructure layer.
MCP (Model Context Protocol) hit 110 million SDK downloads per month in 12 months. David Soria Parra, co-creator of MCP from Anthropic outlined a 2026 roadmap that includes distributing domain knowledge through the same protocol as tool connectivity. MCP is becoming the connective tissue for agent workflows.
Open models are closing the gap on closed models faster than expected. Google DeepMind’s Gemma family is making on-device and offline AI increasingly viable, which could shift the balance towards local versus cloud set-ups. And Google Chrome is proposing WebMCP, an open standard for agent-readable websites. Early days, but worth watching.
The Forward Deployed Engineer Model
The pattern that showed up in the most unexpected places was organisational, not technical. Both the No.10 Downing Street digital transformation team and the Ministry of Justice AI unit described the same approach: small, high-autonomy teams of engineers embedded directly with end users, shipping working MVPs in weeks.
No.10 calls them Forward Deployed Engineers. They recruit from AI labs, big tech, and YC founders at market rates. Short sprints on emerging priorities, then longer-term embedding within departments. The Justice AI unit does the same: multidisciplinary teams hired specifically for “building in messy environments,” sitting with probation officers and frontline staff.
The key insight: political backing is crucial. Without it, the bureaucracy wins. This is the same dynamic in every large institution. The structural problem is identical whether it is government or asset management: slow hierarchies, risk aversion, and procurement cycles designed for a different era.
For investment firms thinking about AI adoption, this is the organisational lesson from the conference. You need a small, empowered team with executive backing, embedded with the people who actually do the work. Not an innovation lab producing demos. Not a consulting engagement producing slide decks. Engineers in the room, building with users, iterating weekly.
Coding Agents Are Impressive, But Slow Down
The recent drawdown in software stocks suggested the market believes software is dead. The conference gave a different perspective. I sat through several sessions where experienced developers, people building real production systems, made essentially the same point: slow down.
Armin Ronacher, the creator of Flask, put it bluntly. AI tools trick engineers into feeling more productive without being more thoughtful. Agents are optimised to write code that runs, not code that is maintainable. The result is messier codebases, more duplication, and entropy accumulating faster than ever. Matt Pocock from AI Hero reinforced this: software engineering fundamentals matter more now, not less. Vague requirements, no shared language, no feedback loops, no architecture discipline. These are the failure modes, and AI amplifies all of them.
The practical takeaway was clear. AI can generate a lot of code quickly, but that is not the same as building a robust system. Poor architecture, weak testing, and messy interfaces do not disappear just because the code is cheaper to produce. In some ways they become more dangerous, because the rate of generation accelerates the rate of mess.
That matters for the investment angle too. There is a temptation to look at coding agents and conclude that experienced developers are about to become much less valuable. I do not think that is right. If the marginal cost of producing code falls, the relative importance of architecture, testing, system design, review, and maintenance rises. Enterprise software is not just code generation. It is controls, modularity, auditability, permissions, failure handling, and long-term maintainability. That is still real work.
I would not read this as “software engineering is dead.” I would read it as the bar moving upward. The low end gets easier. The high end gets more leveraged. And if robust systems still require architecture, controls, and experienced developers, then the economic value may shift away from simple code generation and toward companies that own workflow, trust, and production infrastructure. That is worth paying attention to.
What I Am Taking Back
Evals are moving from nice-to-have to required discipline. Context engineering is becoming a real operating advantage. The future is not more prompting. It is better workflow design.
The conference confirmed something I had already been feeling: developers are living slightly ahead of the rest of knowledge work. What they are solving now, context, evals, observability, reversibility, and controlled autonomy, will not stay inside engineering for long. What developers are learning the hard way about these disciplines is likely to become standard knowledge work practice over the next few years. Investment teams will run into the same problems next. The ones who build those disciplines early will have a real edge.
I compiled a detailed conference report covering all 20 sessions I attended, with notes on each speaker and what it means for investment teams. If you would like a copy, reply to this email and I will send it over. Happy to jump on a call too if any of these themes are relevant to what you are building.
Great insight
“Models are good enough. You are not ready.”
That’s the real takeaway.
Most people are still stuck at prompts
while the real edge is:
evals + context + workflows
Tools didn’t change the game
systems did
If you want to see how this actually translates beyond devs:
👉 All-in-One Google AI: Tools, Workflows & Productivity (https://shorturl.at/hBVBS)